This is a "Remind my future self how to do this, but hopefully it'll be helpful for the rest of y'all too" post! To change the timestamps on files exported from the Mac's Photos app to match the dates that the photos and/or videos were actually taken: 1. Install exiftool if it isn't already installed: brew install exiftool
2. One a a time, run these two commands from the terminal, from the directory where the files are located: for file in *.jpeg; do touch -t "$(exiftool -p '$CreateDate' -d '%Y%m%d%H%M' "$file")" "$file"; done
for file in *.mov; do touch -t "$(exiftool -p '$CreationDate' -d '%Y%m%d%H%M' "$file")" "$file"; done
When those are done, each file's timestamp should match the actual date that the photo or video was taken.
Any The ExtractEmbedded option may find more tags in the media data warnings can be ignored.
Background When copying photos and/or videos from an iPhone to a Mac, the copied photos don't end up as individual files in the Mac's filesystem. Instead, they become part of the "Photos Library" on the Mac, in which all photos and movies are stored in a single "blob" file. Fortunately -- for the purpose of copying and/or backing up photos elsewhere, on non-Apple computers or cloud storage -- the Mac's Photos app provides a capability to "export" photos and videos from the library as individual files. (This is accessed via File menu > Export.) Two export options are provided: "Unmodified Originals" (which tend to have large file sizes); or as JPG, TIFF, or PNG files (for photos), and .mov files for videos (which produces smaller file sizes). Unfortunately, the exported photo and image files have a timestamp (shown as "Date Modified" in Finder) of the time the export was performed -- not the time that each individual photo or video was actually taken. For me, having the date shown for each file in Finder match the date that the photo/video was originally taken is a lot more useful. Hence, the procedure described earlier in this post to make that change. "CreateDate" versus "CreationDate"
You may have noticed that in the two terminal commands above, the former uses the EXIF tag "CreateDate", and the latter, "CreationDate". For some reason -- for photos and videos exported using the Photos app on macOS Ventura 13.4, and originally taken on an iPhone running iOS 16.5 -- exported .jpeg and .mov files, respectively, have inconsistent sets of EXIF tags. The EXIF tags on a paritcular file can be inspected using exiftool via a terminal command like: exiftool -s my_photo.jpeg
For my exported .jpeg files, this produces output like (with irrelevant tags excluded): CreateDate: 2023:07:04 09:51:12
There's no "CreationDate" tag present.
For my exported .mov files, the output is like: CreateDate: 2023:07:22 14:04:56
CreationDate: 2023:07:04 13:39:20+02:00
So both CreateDate and CreationDate values are present; however, here, "CreateDate" is the timestamp of the Mac Photos app export, and CreationDate is the actual time the video was recorded. I'm sure there are excellent reasons behind this seemingly-inconsistent state of affairs; I am not aware of what those might be. 😅 In any event, it was easy enough, one I investigated and figured out what was going on, to split the exiftool command into two separate parts, for the EXIF tags that are actually present and correct in the .jpeg and .mov files, respectively. Credit for the original exiftool command that I adapted here goes to Daniel Schofield on the Ask Different Stack Exchange site.
My team at work was recently facing a problem where "magic link" login URLs being sent out via SMS (text message) were "broken" when received by iPhone users. Only part of the URL's query string portion was properly rendering as part of the link; the remainder -- despite not being separated by a space, or any URL-invalid characters -- was showing up as plain text: A magic link in this context is an URL that includes a secure, tamper-evident key which identifies the user, and allows them to log in to the application that sent the link, in lieu of having to enter a password. (This has security pros and cons; that linked article provides a nice summary.) My team is using JWT as the magic link key. JWTs are encoded into three portions, separated by period characters (remember that, it's important later!): A header; the message payload (including things like the user's ID, and the key's expiration time); and the signature verification. In our case, only the first portion of the JWT value, the header, was being rendered by iPhone recipients of our SMS message as a part of the clickable hyperlink. The remaining two portions were showing up as plain text. This broke the magic link! While it still directed users to our site, it was unable to log them in.
I spent the day yesterday performing an investigation into why this was happening.
For starters, asking Google about the maximum length of an SMS message yields the answer "160 characters." Here in 2023, as far as regular users are concerned, this is no longer really true. (When's the last time you were composing a text message, and your phone stopped you from sending your message because it was longer than about half a Tweet?) All modern providers use "SMS concatenation" to, behind the scenes, break a long SMS message into multiple parts, and then seamlessly stitch those parts back together into a single message for the recipient. I hypothesized: Perhaps Apple's implementation of SMS concatenation doesn't work when the URL itself is longer than 160 characters (as our magic link login URLs including a JWT token are)? No; I was able to disprove this by sending myself a text message with such an URL; it arrived in one piece, no problems. (As an aside, I started out doing these tests by using the web UI of my work's existing Twilio account to send messages to my personal iPhone's number. This worked fine; I pretty quickly determined, though, that I could more expeditiously test by just using my Mac's Messages app to send messages to my own phone number. This produced the same results, as far as the received message ending up broken or not.) Perhaps SMS concatenation doesn't work when the query string portion of the URL is longer than 160 characters? No; disproved by sending myself such a link, which once again was delivered in one piece, as expected. Perhaps the problem is when a single query string key-value pair -- or just a query string value -- is longer than 160 characters? No; I was able to successfully send myself messages (using the string "1234567890" repeatedly as the query string value to achieve the target length) in with such query string values excess of 500 characters in length, no problems. My testing went on like this. I was consistently able to reproduce the broken link behavior using an actual (Dev environment) magic login link; the behavior of any particular URL being broken or not appeared to be consistent/deterministic, at least. Further, by trimming down certain portions of that URL, the link would be correctly delivered in one piece. By testing many message and URL variants, and recording for each one whether it succeeded or failed to deliver properly, along with the lengths of the various portions of the message text and the URL, I was finally able to pin down the problematic behavior. Here it is, in plain English: For a given query string value: If that value contains any URL-valid punctuation characters (i.e. non-alphanumeric characters): If any portion (or "slice") of that query string value beyond the first portion, when separated/sliced by punctuation characters, is 302 characters or longer, the URL will break (on Apple devices). If all such portions are 301 characters or shorter, the URL will render correctly. Recall that JWT values consist of 3 portions -- separated by period characters? This meant that if the token's 2nd (payload) or 3rd (signature) encoded portions were in excess of 301 characters, the resulting link would be broken when delivered to an iPhone. (Notably: It's only Apple's handling of SMS messages, in their Messages / iMessage app on iPhone and on Mac, where links render as broken in this particular way. In my testing with Android clients, and with Google Voice, all links that I tested with were delivered correctly, regardless of length!)
Here are a few examples of working and broken URLs (when received by an Apple client). To save space (and to make this post less ugly!), instead of actually spelling out URL portions of 300+ characters, I'll represent such portions with the number of characters in that portion. The following links, when delivered to and viewed on an iPhone, or in Apple's Messages app on a Mac:
https://example.com?key=400 (OK; there are no punctuation characters in the query param value) https://example.com?key=10.302 (BROKEN; the second portion of the query param value is longer than 301 characters) https://example.com?key=301.301_301 (OK; no portion of the query param value is longer than 301 characters) https://example.com?key=200~200.400 (BROKEN; the 2nd portion is ok, but the 3rd potion is longer than 301 characters)
https://example.com?key=400-50 (OK; only the first portion of the query param value is longer than 301 characters, and that doesn't manifest the problem)
https://example.com?key1=400&key2=400 (OK; the both query param values here consist only of "first portions", which don't manifest the problem) To work around this problem -- and to produce links that are some what less nasty-looking on clients that render the entire URL -- I'm planning on making a pair of changes to our magic login tokens: 1. Reducing the payload content to "essential" values only. Namely, the user's email address, and an expiration date/time value. This will cut down on the middle "payload" portion of the JWT. 2. Using HS256 instead of RS256 as the signing algorithm. For our specific application and usage scenario, HS256 will provide sufficient security; but HS256 signature values are significantly shorter in length. All of the aforementioned testing was done in June 2023 using an iPhone 12 running iOS 16.5.1; and a MacBook Pro running MacOS Ventura 13.4. Perhaps Apple will address this issue in future software versions? (But if this particular bug isn't at the top of their priority list, I certainly can understand why not. ☺)
Hopefully this post may be helpful to any of y'all out there who are researching why your SMS messages that include JWT magic link login URLs (or other long URLs including long query string values) being delivered to iPhone clients aren't rendering properly!
What happened?At work this past week, I was alerted to a problem where a background job which processes incoming messages from a particular queue had slowed down dramatically. As a result, a significant delay had developed in providing certain event notifications to our customers.
Our monitoring tooling showed that the culprit was a particular SQL Server stored procedure -- one that gets invoked as a part of processing each message from the queue. Execution time of that sproc had suddenly increased from near-instant to an average of 4 seconds, with spikes up to around 20 seconds. (The queue processing job is multi-threaded, so we were still processing about one message per second, but that was no longer keeping up with the incoming volume of messages during the busy hours of each day.) No code deployments or changes to the environment had been made around the time of the initial slowdown; this problem had started occurring without an obvious root cause. Our investigation
The stored procedure in question comprises about a dozen individual SQL statements and queries. It wasn’t immediately clear which individual statement in the sproc was responsible for the slowness.
After a few initial investigative paths didn’t yield results, I decided to run a short trace on the live production database. The trace revealed that one particular SELECT query was consistently taking a long time to run during each run of the stored procedure.
Interestingly: When I ran that same SELECT query SQL manually, it completed near-instantly. However, when I ran some minor variations on that SELECT query, they did take a long time to execute. Execution plans and indexes
SQL Server internally generates an “execution plan” for each query that it runs, whereby it decides how it will go about performing the operation that the query's SQL calls for. The SQL Server Management Studio tool is able to display these execution plans in a nice graphical format.
When the problematic SELECT SQL was run manually, the execution plan showed that it was – correctly – leveraging an existing index on the target table. That index had been originally added to support this specific query. It includes fields needed by the query’s lookup criteria.
Looking back at the results of the trace, the problematics SELECT queries being run during execution of the stored procedure were being run using a different execution plan – not leveraging the custom-designed index at all! A full table scan was being run by SQL Server to gather the query results. As that table currently sits at a total row count of over 150 million, those queries were taking a while to run! The specific SQL being run (simplified a bit here for readability) was:
SELECT TOP 1 ID
FROM myTable t
WHERE t.CreationDate > DATEADD(day, -30, GetDate())
  AND (t.Email = @Email OR t.PhoneNumber = @PhoneNumber)
  AND t.CompanyID = @CompanyID)
ORDER BY t.ID ASC
The custom index includes the following fields: - CompanyID
- Email
- CreationDate
- PhoneNumber
Can you spot the problem?
…
Take a look at the ID field. That field isn’t part of the index; but it is being used in the SQL’s ORDER BY clause! And that clause, as it turns out, is used by the database as one of the factors in how it seeks for the single (TOP 1) row to return.
Through its own inscrutable internal algorithms, prior to April, SQL Server had been using an execution plan that did leverage the custom index for this query, despite the presence of the ID field in the ORDER BY clause. After April, some tipping point in the database’s characteristics was evidently hit that made SQL Server decide to no longer use that index in its execution plan during runs of the stored procedure.
The fix was to adjust the SELECT query to ORDER BY CreationDate, rather than by ID. This had the same logical effect with regard to selection of the returned row; and it got SQL Server to once again use our custom index while running the stored procedure, resulting in the resumption of speedy performance in processing of messages from the queue. How did we verify that the fix worked?
- We observed that new records continued to be inserted correctly (and now, a lot more quickly!) into the database table.
- Execution times for the stored procedure went way down. We could see this both from the database itself, and from the our queue's web interface – the green line here is the rate of messages being processed off the queue, with the fix having been applied just after the 10:20 mark:
So what are the lessons here?- Having the ability to determine which specific SQL statement was the root cause of the downstream slowness was key to being able to devise a fix. (The fact that our monitoring instrumentation only reported to the granularity of which stored procedure was running slowly -- but not which individual SQL statement within the sproc was slow -- made this trickier.)
- The availability of multiple weeks of monitoring data from our instrumentation did make it quick and obvious to confirm that there had been a dramatic change in performance from one of our stored procedures, which was the cause of the problem.
- When a particular SELECT statement is slow, ensuring that a properly-matching database index is in place – and that index is being applied to live queries in the expected manner – is a very good thing to check!
I recently did troubleshooting for, and managed to successfully fix, an issue where HTTPS connections to a specific remote server were failing to be made successfully. The client computers affected by the issue were a pair of servers, running Windows 2012 R2 and Windows 2008 R2, respectively. For the purposes of this post, I’ll use https://tls.example.com as the URL of the remote server. The Problem Symptom 1: In a C# program, an attempt to establish an HTTPS (SSL / TLS) connection to https://tls.example.com failed. Error message: “The request was aborted: Could not create SSL/TLS secure channel.” - The program did work fine to make connections to all other HTTPS URLs that we had tried.
- The exact same C# program worked fine when I ran it from my local workstation as the client PC (connecting to the same https://tls.example.com remote server).
Symptom 2: In Internet Explorer 11, attempting to connect to https://tls.example.com failed. Error message: “Turn on TLS 1.0, TLS 1.1, and TLS 1.2 in Advanced settings and try connecting to again. If this error persists, contact your site administrator.” 
- However, connecting to https://tls.example.com using the Chrome browser from that same client PC worked fine.
- Connecting to https://tls.example.com from my local workstation using Internet Explorer 11 also worked fine.
The Solution Note: This solution will only help if the remote server is configured with an SSL key that has an ECDSA (not RSA) signature, but all of the the cipher_suites that the client PC is configured to support are RSA (not ECDSA). Note 2: If you’re reading this post after August 2016, check and make sure the new cipher_suites value that you add is one that’s still cryptographically valid. These things tend to change over time! Note 3: Don’t use Registry Editor (as suggested here) unless you know what you’re doing. It can permanently damage your PC. In my case, the problem was caused by there being no match between the set of cipher_suites supported by the client, and the set of values that the server was able to accept. Specifically, in my case, the server had an SSL key signed with ECDSA (not RSA), and my problematic client PCs were configured to use only ECDSA (not RSA) cipher_suites. This caused SSL handshaking to fail after the initial “Client Hello” step. I was able to fix this by adding a ECDSA value to my client PC’s set of cipher_suites: On the client PC: - Open the Registry Editor.
- Navigate to HKLM/SOFTWARE/Policies/Microsoft/Cryptography/Configuration/SSL/0010002
- Edit the existing comma-separated value, and add a new value to the end that’s supported by the client OS, is cryptographically secure, and works with a key with an ECDSA signature. The value I used: TLS_ECDHE_ECDSA_WITH_AES_128_GCM_SHA256_P256
- Reboot.
Investigation Details The remainder of this post details the investigation that led me to the above solution. SSL / TLS protocol mismatch? I’ve run into SSL handshaking problems before caused by a protocol mismatch. For example, the client specified that it would only connect using SSL 3.0 or TLS 1.0, but the server would only accept TLS 1.2. However, that did not seem to be the cause of the issue here (despite the Internet Explorer error message): - In my C# program, I was specifying that the client accept any of TLS 1.2 | TLS 1.1 | TLS 1.0.
- In Internet Explorer’s Advanced Options dialog, I confirmed that the checkboxes for TLS 1.2, TLS 1.1, and TLS 1.0 were all already checked (again, despite the error message).
- In Firefox, by clicking on the green lock icon in the address bar after successfully connecting to the remote website, I confirmed that the connection was secured using TLS 1.2.

As far as I could tell, both the client and server should be agreeing on the use of TLS 1.2. Thus, probably not a protocol mismatch issue. SSL certificate trust chain issue? When I asked myself the question “So what’s different between my local PC (where things work fine) and my server PCs (not working)?”, the first answer I came up with was, maybe the installed trusted SSL root certificates? However, that theory turned out to be a dead end in this case. When I used the “Manage server certificates” / “certlm” tool to look at the installed certificates on my PCs at Certificates > Trusted Root Certification Authorities, although there were some differences between the root certs on my local Windows 10 PC versus the root certs installed on the Windows Server 2012 R2 PC, that didn’t turn out to be the cause of the problem. Additional symptom: System event log error My first clue to the actual problem was a Windows System event log error that I noticed would be logged whenever I reproduced the HTTPS connection failure in Internet Explorer or my custom C# program: “A fatal alert was received from the remote endpoint. The TLS protocol defined fatal alert code is 40.” A helpful MDSN blog post defined that error code of 40 as “handshake_failure”. Network traffic sniffing using Microsoft Message Analyzer As suggested by another very helpful Microsoft blog post, I installed Microsoft Message Analyzer. (It turns out that I needed to install the 64-bit version of Analyzer to match my OS, even though as far as I know, browsers typically run as 32-bit processes.) Using Message Analyzer turned out to be easy. I just did the following: - In Analyzer, hit the “New Session” button;
- Selected “Local Network Interfaces”;
- Hit Start;
- Switched windows to my C# program, and reproduced the issue;
- Switched back to Analyzer, and hit the Stop button.

I filtered out all irrelevant events captured while my session was running by applying this filter: (*Source == "www.example.com" or *Destination == "www.example.com") and *Summary contains "Handshake" (Where both instances of “www.example.com” were replaced with the actual host to which I was connecting.) On my local PC where the HTTPS connection was working, the Message Analyzer results included a “Handshake: [Client Hello]” message originating from my local PC, followed by a “Handshake: [Server Hello]” originating from the server. However, on the Windows Server 2012 R2 machine where the the connection was failing, I could see the “Handshake: [Client Hello]” from the local machine was followed by an “Alert” reply from the server! Doing a right-click | Show Details on the Alert reply, I could see that it contained a body message of “Level 2, Description 40”. This reply must have been what the System Event Log was picking up to generate that message that I’d noticed earlier. Comparing the successful and unsuccessful Client Hello messages At this point, I’d narrowed down the difference between the succeeding and failing environments to the differing server replies to the initial “Client Hello” step of SSL handshake. Still in Message Analyzer, I did another Show Details to compare the contents of the “Client Hello” on my Windows 10 PC (working) and my Windows Server 2012 R2 machine (not working). The significant difference turned out to be the cipher_suites parameter in the body of each PC’s “Client Hello” message. 
As I learned, the cipher_suites parameter contains the list of encryption settings which the PC sending the message is able to handle. The idea is that the server picks the one from that list that it prefers, sends a “Server Hello” reply that includes the selected cipher suite, and the two sides use that to securely communicate. It turns out that while my Windows 10 PC (working) was sending a selection of 33 cipher_suites values that it was able to support, the Server 2012 R2 PC (not working) was sending only 11 cipher_suites values! Each cipher_suites value, while it appears in the raw message body as an integer, “translates” to a descriptive string value like: TLS_ECDHE_ECDSA_WITH_AES_256_GCM_SHA256. (Message Analyzer helpfully performs this translation when displaying the values in the cipher_suites value under the “body” value, as is mostly visible in the screenshot above.) The Microsoft article Cipher Suites in TLS/SSL provides a very helpful picture of what the parts of those cipher_suites values mean, which I’ll borrow and display here: 
Taking a closer look, the 33 cipher_suites values from the Client Hello message Windows 10 PC (working) included a mix of cipher_suites values contained a mix of RSA, DHE, and ECDSA as the Signature value. The 11 values from the Server 2012 R2 PC (not working) all had RSA as the Signature value! A Certificate Signing Algorithm Mismatch? Discovering that the not-working Server 2012 R2 PC was effectively saying that it would only support RSA as the cert signing method immediately suggested a new likely theory: If the server cert was signed with something other than RSA, the SSL handshaking would fail. Sure enough, drilling further down into the cert details in Firefox showed that the cert was signed with not RSA, but ECDSA: 
In essence, the failing SSL handshaking conversation was going like this: - Client [Client Hello]: Hey, let’s talk securely, using any of these methods (…), as long as you’ve got an RSA-signed cert!
- Server [Alert]: Sorry, nope, I can’t do business along those parameters. Bye!
Getting the Server 2012 PC to accept an ECDSA certificate A great blog post by Nartac Software on how their IIS Crypto tool works pointed me to the solution. A Windows registry key mentioned in that article contained the same set of cipher_suites values that I was seeing in the problem PC’s Client Hello SSL handshake message: HKLM\SOFTWARE\Policies\Microsoft\Cryptography\Configuration\SSL\00010002
In the Server Hello SSL handshake message on my working Windows 10 PC, I could see that the cipher_suites value that the server had selected to successfully communicate with was:
TLS_ECDHE_ECDSA_WITH_AES_128_GCM_SHA256
From that same article, another registry location has the list of supported cipher suites on the server:
HKLM\SYSTEM\CurrentControlSet\Control\Cryptography\Configuration\Local\SSL\00010002
Looking in that registry location on the Server 2012 R2 PC, I saw that one of the supported values was
TLS_ECDHE_ECDSA_WITH_AES_128_GCM_SHA256_P256
With the cipher suite portion of that key being a match for the accepted value that had been accepted by the server in the SSL handshake from my Windows 10 PC, I edited the comma-separated list of cipher suite values from the first 00010002 registry key above to include this additional cipher key value. Finally, I rebooted the Server 2012 R2 PC (since a reboot is required to make the change take effect).
After the reboot, the problems were solved! Internet Explorer was successfully able to connect to the target website, and my C# app was also able to successfully establish an HTTPS connection.
So how had this happened?
I posed the question to the failing client PCs’ hosting provider: Are Windows Server 2008 R2 and Windows Server 2012 R2 machines configured by default to only accept RSA SSL certs, or is this something that the hosting provider configures in their “default” images?
The answer, it turned out, was neither of the above. Instead, the missing non-RSA cipher suite values had been intentionally removed in an “server hardening” task performed some time in the past. This probably made sense originally, under an assumption that these servers would never themselves be acting as the client side of an HTTPS connection, and therefore for the sake of reducing attack surface, could have cipher suites with signature types other than the servers’ own cert signatures disabled.
I got a call from my wife while I was at work yesterday: There was a problem with our primary home PC, which runs Windows 7. As the machine was booting, after the BIOS data appeared followed by the graphical Windows 7 “loading” logo on the primary monitor, the primary monitor went into sleep mode (as though it had been unplugged from the PC). By moving the mouse around, the mouse cursor was visible on the secondary monitor, but clicking it (including right-click) didn't do anything. Getting home, I saw the problem for myself. I concluded that the Windows logon screen was being displayed on the primary monitor -- I just couldn't see it because the primary monitor was off. I was able to log onto the machine blind (by arrowing over to my user profile, hitting Enter to activate it, keying in my password, and hitting enter again to log in). Once in to Windows, I was able to make my secondary monitor become the primary monitor, via right-click on the desktop, selecting Screen Resolution from the Right-click menu, “rescuing” the Screen Resolution window from the sleeping primary monitor onto the secondary monitor to make it visible, then checking the “Make this my main display” checkbox on the secondary monitor. I spent pretty much the entire evening troubleshooting the problem. Here the long list of troubleshooting steps I tried: Verify both ends of the monitor cable were firmly seated: It was seated properly. Cold reboot: No change in behavior. Install the latest video driver (for the video card, an NVidia Geforce 6800 GT): No change in behavior. Install the latest monitor driver (for the primary monitor, a ViewSonic VX2035wm connected via DVI): No change in behavior. Uninstall the monitor drivers (and let Windows reinstall them after rebooting): No change in behavior. Uninstall Microsoft Security Essentials (which I had just recently installed) (on the theory that MSE could somehow be seeing the ViewSonic monitor driver as malware): No change in behavior. (I reinstalled MSE again afterwards.) Restore the system to a restore point from a few days prior (when I know the monitor had been working fine): No change in behavior. Reboot into Windows Safe Mode: This actually did get the logon screen, and then the Windows desktop, to display properly on the primary monitor. I was even able to increase the screen resolution from the safe mode default (1024x768, I think) back to the native resolution of 1680x1050. I was not able to use dual-monitor display, though; the Screen Resolution dialog only detected the primary monitor while in Safe Mode. Rebooting again (back into normal mode) brought me back to square one. Uninstall the video driver (then reboot): After rebooting, the behavior was similar to safe mode; the primary monitor worked, but not the secondary. Upon reinstalling the NVidia video driver and rebooting once more, it was again back to square one. Reseat the video card (with the PC powered off, then boot back up): No change in behavior. Unplug the secondary monitor (leaving only the primary monitor plugged in) (then reboot): This didn’t help. I still got, after rebooting, the BIOS information visible, the graphical Windows 7 logo visible, then blank screen / sleeping monitor. Swap the ports that the two monitors’ DVI cables were plugged into, then reboot: This actually caused me not to get anything display on either monitor. I changed it back afterward. Check BIOS settings: I didn’t notice anything unusual, or any settings that I could change that might be likely to fix the problem. I ended up leaving everything alone. Finally, after all that, I hit upon a good solution: I replaced the video card. Specifically, (after powering both machines down and unplugging them, of course), I pulled the GeForce 6800 GT from my primary machine and set it aside; then, I pulled the GeForce GT 430 from my HTPC (leaving that PC with just the motherboard’s onboard audio/video), and installed that card in my primary PC; then I booted the primary PC back up. After doing that, and letting Windows install the NVidia display driver, both monitors came up with no problem. So even though I had been pretty convinced initially that I was looking at a software problem, probably a driver problem of some kind (given that the primary monitor worked fine at boot time, and even displayed the graphical windows logo, and also worked fine in Safe Mode), the problem apparently was that my GeForce 6800 GT decided to (partially) fail on me. It was actually my lovely wife that made the astute observation that the fact that I had been fairly recently running that card at a scorching hot 100+ degrees C probably hadn’t helped matters! Note that I don’t recommend that anyone else who encounters this issue (and comes across this blog post via a search) run out and spend $$$ to replace your video card as your first option. In researching this issue online during the course of the troubleshooting, I did run across some reports from others of this same problem (screen goes blank after displaying the Windows logo during boot) who were able to solve their issue by doing one of the other steps that I tried, such as uninstalling and reinstalling video drivers. For the time being, I’m in good shape with my workaround. The lower-end but newer GeForce GT 430 is actually almost as good a video card as the original 6800 GT; and the HTPC can play TV and movies fine with the onboard video. I guess this gives me something to put on my birthday list for my birthday coming up later this year!
At work, I recently had the chance to upgrade to a new development laptop PC, a Thinkpad T520 running Windows 7. The machine is excellent, with one weird exception: In Firefox (and only in Firefox), when keying in text into a text entry field in a web page or into the browser address bar, the caret (i.e. the text entry cursor) would sometimes appear to be “distorted” or “corrupted” – that is, some “garbage” pixels would appear around the caret whenever I moved it (either by typing in a character, or by using the arrow keys). Problem Details The problem is hard to explain, so here’s a screen capture of a particularly severe example that occurred when I was entering text into a textarea. The caret in this cropped screen shot is between the “2” and “5” in “8/25/2011”; note all the other weird stray black and white marks in the text. (I added the red oval to the screen capture to show the area in which the “corruption” was appearing. 
After waiting a little less than a second without moving the caret, the problem would go away – the “corruption” would disappear from the display. However, the problem would come right back upon moving the caret again. The caret itself would also sometimes not appear until the “corruption” went away, which made text editing surprisingly difficult – a frustrating problem. Investigation The problem would only occur in Firefox, not in other browsers such as Internet Explorer 9, or in any other applications I tried (such as Eclipse, Word, and Notepad). Experimenting, I found that the problem would not occur when Firefox was started in Safe Mode (via Firefox menu | Help menu | Restart with Add-ons Disabled). However, I tried running Firefox in normal mode with all extensions and add-ons manually disabled, and that didn’t help. I tried setting up a new Firefox user profile, and that didn’t help either. I also noticed that beyond the issues with the caret, the actual rendering/shape of letter character glyphs being typed into Firefox was affected. The characters themselves appeared “wrong” when Firefox was running in normal mode, but they appeared normally with Firefox in safe mode. Here are two cropped screen shots I took of a bunch of “f” characters being entered in to the address bar, the first in normal mode, the latter in safe mode: 

Here’s a zoomed-in view (again, normal mode first, then safe mode): 

Note that in the former image (Firefox normal mode), the “f” glyphs do not appear the same as one another and have some faint red/yellow/blue/green aliasing (blurring), whereas in the latter screen capture (Firefox safe mode) each “f” glyph is identical and has no aliasing (look at the unzoomed image). At this point I was suspicious of some kind of issue with my video card. The normal first course of action with a suspected video card behavior issue would be to update video card drivers. When I checked, though, I found that I was already running the latest drivers for my video card (an NVidia NVS 4200M). Google was initially no help; all the searches that I tried for terms like “firefox cursor corruption” or “firefox caret appearance” resulted in pages talking about the Firefox caret navigation feature (F7 key), which was not the issue here. Solution I hit upon the solution when I changed angles of attack and Googled for “firefox safe mode”. The first result was a Firefox help article describing safe mode, which linked to a Mozillazine knowledge base article with more details on Firefox safe mode. That article in turn had a list of about a dozen bug repots related to safe mode, one of which was Bug 591139 - Disable hardware acceleration in safe mode. Aha – that sounded like a video-related issue! Reading through that ticket, I learned that starting in Firefox 4, a feature called “hardware acceleration” (with which I was previously unfamiliar) is disabled when Firefox is in safe mode. Hitting up Google once more, this time for “firefox disable hardware acceleration,” I was led to a setting in the Firefox options menu: Firefox menu | Options | Advanced | General tab | Use hardware acceleration when available. I unchecked that setting, restarted Firefox, and that did it – the problems with the caret corruption/garbage and the malformed character glyphs no longer occurred! So apparently Firefox has an on-by-default feature where it uses hardware acceleration, presumably from the local PC’s video card, further presumably to improve its performance and/or ease load on the primary CPU. However, having disabled this setting, I haven’t noticed any appreciable difference in performance. I don’t know who is to blame for this issue – bad video driver, bad video hardware, Firefox itself, some combination of those, or something else entirely – but for the time being, I’m just satisfied that the issue is resolved for me! I hope this saves some frustration and/or troubleshooting time for anyone else experiencing this odd issue!
A couple of weeks ago, I had a hankering to play a classic RPG game. After looking around at the available options for systems that I own, I decided to pick up a copy of Dragon Quest V for the Nintendo DS. Unfortunately, even though the game was released in the U.S. just last year (2009), it’s already out of print, so I went to eBay. There were just a few copies of the game for sale; most were going for around $30, but one “cartridge only” auction was going for a “buy it now” price of $17. The auction was from a seller in New York and nothing about the auction at the time made me suspicious (though perhaps it should have – keep reading), so I went ahead and bought the auction. I got the game in the mail a few days later, and played it. The game didn’t slide particularly smoothly into my DS Lite – it was a slight “pressure fit” – but I didn’t really think anything of it at the time. The game started up with no problems. After viewing the introductory sequence (showing the main character’s birth) and proceeding to the first playable portion of the game (where the main character, now a child, is travelling on a small ship), I ran into a problem: I couldn’t figure out how to get off the boat or otherwise advance the plot. I’d talked to all of the NPCs on the ship several times each, and explored everywhere that I could; after doing that, there just seemed to be nothing else to do, and no enemies at all to fight. Eventually I consulted gamefaqs, but none of the FAQs gave any special attention to the boat scene – they all just seemed to assume that advancing past the scene would present no problem at all. I searched Google for terms like “dragon quest v boat stuck,” and got my first obvious clue that something was not right. Apparently the programmers at Square Enix, the game’s developer/publisher, included code in the game that when playing a counterfeit copy of the game, the player would experience game behavior exactly matching the problem I was having – the game would just never advance past the boat scene, and the player would basically be stuck. However, all of the references to this behavior that I found were in reference to players playing an unauthorized copy of the game via an emulator. I, on the other hand, was playing what I had thought to be a legitimately-purchased copy of the game, on actual physical Nintendo DS Lite hardware. Still, the behavior I was seeing made me strongly suspect that I’d been sold an unauthorized, or “bootleg,” copy of the game.  Researching further, the copy of the game that I’d been sent had a serial number on the front of the cartridge of “NTR-CDXP-EUR.” Googling on that, I found two things:
- That serial number actually apparently was assigned to some game called “Driving Theory Training” (and not to Dragon Quest V);
- A few forum posts from other people saying that they had a DS cartridge with that serial number (of various other games, neither Dragon Quest V nor “Driving Theory Training”) and they were suspicious that the cartridge was a bootleg.
This convinced me that I did have a bootleg cartridge on my hands. This made me pretty unhappy – I purchase all of my games legitimately, and don’t “pirate” games. If a particular game costs more than I’m willing to pay to play it, then I simply don’t play it. I contacted the seller, and he agreed to refund my money upon my shipping the cartridge back to him. He claimed to be unaware that he was selling bootleg copies of games, and said that he would take the issue up with his supplier. Ultimately I’m not sure exactly how honest he was being, but he did end up refunding my money (less the the $3 and change that I paid to ship the game back to him). So: What should I have done to avoid buying this game to begin with, and what should I do to avoid buying counterfeit game cartridges in the future? None of the following points taken on its own is a certain indication of a bootleg game; however, all together, they may be adequate cause for being suspicious of a particular auction: - Price: The low sell price of this game relative to other auctions for the same (somewhat rare) game should perhaps have been cause for suspicion.
- Contents: The fact that the game was “cartridge only,” rather than including case and manual, should perhaps have been cause for concern. (Again, certainly there are many legitimate “cartridge only” auctions, but this taken in combination with other factors should have raised a red flag.)
- Origin: This particular auction was shipping from New York rather than from China; I have seen, though, some other sales of unusually low-priced games originating in China that are pretty obviously for counterfeit copies.
- Image: The auction listing included an image of the cartridge, but it was blurry, and the serial number on the front of the cartridge was unreadable.
I couldn’t have determined this from looking at the auction online, but when I tried physically lining up the counterfeit game next to a few of my legitimate DS games, the difference was fairly obvious. Although the counterfeit cartridge on its own was pretty legitimate-looking upon a casual inspection, the size and shape of the cartridge were just barely “off” compared to the other legitimate cartridges, which were all identical to one another. (This was the cause of the issue I mentioned of the bootleg cartridge not quite being an easy fit into my DS Lite, like legitimate games all are.) At least this incident was a learning experience -- that bootleg console game software is out there and is being sold. In the future I will likely take one or both of the following steps before bidding on an auction that seems like it might be suspect: - Just ask the seller if the game is a genuine copy. If the answer is anything other than an honest-seeming answer along the lines of “yes, absolutely,” then don’t bid.
- Ask the seller what the serial number on the front of the cartridge is (if it isn’t visible in a photo on the auction). If it isn’t what it should be, then certainly do not bid.
I might never have realized that I was playing a counterfeit copy if there hadn’t been this particular variety of DRM built into the game. I’m not normally a big fan of DRM (who is?), but I understand the necessity of it; still, I wish this DRM had been of a “fail fast” nature (i.e. have the game refuse to run at all if it identified itself as being counterfeit) – then I wouldn’t have lost a couple of hours of my evening to playing a broken game and researching the problem. I’d much rather have just had the opportunity to honestly purchase a legitimate copy of the game (and avoid supporting whatever pirate created this unauthorized copy) the first time.
I was just re-reading a piece of code that I'd written earlier today which attempts to detect duplicate customer records in a particular database table, when I came across a misspelling in a comment: I'd misspelled the word "duplicate" as "dupliate." I corrected the typo, and continued reading, when I came across another instance of the same misspelling: "dupliate" instead of "duplicate." Curious now, I did a search of the source file for other instances of the misspelled word "dupliate"; to my surprise, I found a LOT of instances of that misspelling (all in my own hand-entered comments, so not due to intellisense or copy-paste)! At this point, I suspected that the problem was due to some factor beyond simple human error, so as an experiment, I tried just typing the word "duplicate" several times in a row (and paying attention to be sure that I actually was hitting the C key). This was the output: dupliate dupliate dupliate dupliate dupliate duplicate dupliate The problem was reproducible almost every time. I briefly experimented further: - The problem WAS reproducible in text editors other than my IDE (Eclipse).
- The problem was NOT reproducible when I typed slowly and deliberately, being sure to hit each individual key one at a time.
- The problem was NOT reproducible using my machine's built-in keyboard (an IBM/Lenovo Thinkpad T60 laptop); only when using the external keyboard (a "standard" qwerty / U.S. layout black Dell-branded PS/2 keyboard, part number 04N454).
I discovered that the specific problem was that while the L and I keys on the keyboard were being pressed, presses of the C key would be dropped/ignored. I found that every other letter key on the keyboard worked with L and I held down; just not C! So what was happening here was that in typing "duplicate," I apparently was typing the C (with my left hand) before I'd let go of the L and I keys (with my right hand) -- or at least before the L and I keys had "popped back up" -- and consequently, the C key press was getting dropped. Now that I'd realized what was going on, I remembered that this is a typical hardware limitation of keyboards: certain keys cannot be pressed in combination with one another. I hadn't thought about this in years and years -- since back when I used to play 2-player games on the PC that would have both players using the keyboard on the same PC simultaneously. The old (1990) PC game Star Control actually came with a utility called "Key Jamming" for working around this very issue: The utility would allow you to experimentally hold down various key combinations, and tell you which ones the PC could "see," to allow you to customize the game's keyboard controls on your machine's keyboard such that players in a two-player game wouldn't end up "locking out" one another. It's unfortunate that the Dell 04N454 keyboard has this particular limitation. I'm not sure what I can do to work around it, though, short of just needing to have extra awareness of my spelling (particularly in non-spell-checked environments such as IDEs) -- or else looking into using a different keyboard which isn't affected by this particular limitation!
For most of the time I've had my ThinkPad T60 laptop (running Windows XP SP2) and Advanced Mini-Dock, when I would undock the laptop from the docking station, the ThinkVantage Access Connections application would automatically and successfully enable the machine's wireless radio and connect me to the local wireless network. However, following a recent (May 2008) round of system software updates installed via ThinkVantage System Update, this no longer worked. After undocking, the wireless connection would not automatically be made, and when I tried to manually connect using ThinkVantage Access Connections, the attempt would fail on the first step of the process, "Applying wireless settings." 
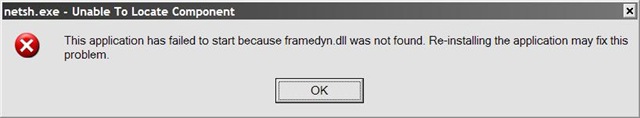
After encountering this failure, I would be able to get the wireless to work correctly once again by rebooting the machine. (Needless to say, I wasn't happy with this workaround, due to the delay involved in rebooting, and the need to close all open applications.) The Fix - Executive Summary I was able to fix the issue on my machine by reverting from ThinkVantage Access Connections version 4.52 to version 4.42. The Fix - Long Version / Investigation On one recent occasion where I undocked and subsequently encountered the issue, the ThinkVantage Access Connections service process, AcSvc.exe, crashed (with the typical Windows XP "This application has encountered a problem and needs to close" crash dialog). I restarted the process (via the ThinkVantage Access Connections application shortcut on the Start menu), and after doing that, the wireless started working again, with no reboot involved. This led me to believe that the issue was with the Access Connections software. I reproduced the undock issue again, and this time manually killed the AcSvc.exe process (via Windows Task Manager), and restarted it, and that once again got the wireless networking to work. So at that point I at least had a better workaround than needing to reboot. I continued to investigate the issue, and found a post on the Lenovo Support Forums indicating that another ThinkPad owner was having an apparently unrelated problem with AcSvc.exe, but that he was running Access Connections version 4.52, and that he had been able to resolve the issue by reverting to version 4.42. I checked my ThinkVantage System Update log, and noticed that an upgrade to Access Connections 4.52 had been among the changes in the recent round of updates I had installed. A co-worker who also had a T60 and was having no wireless issues also reported that he was running Access Connections 4.42. Armed with all of this information, I decided to try reverting to Access Connections 4.42 to see if that would resolve the issue. I was somewhat nervous about doing this, since if the Access Connections installer didn't do a good job of handling the case of installing an older version of the software on top of a newer one, I could conceivably left in a broken state where my network connectivity (both wired and wireless) might not work at all. To try and mitigate this risk, I backed up the registry entries and program files for Access Connection 4.52 before proceeding. Fortunately, the Access Connections 4.42 installer had good handling for installing over a newer version: it recognized that I had a newer Access Connections version installed, and (with my approval) uninstalled the existing version before installing the 4.42 version. Following a reboot, with Access Connections 4.42 installed, the laptop now once again automatically and successfully connections to the wireless network following an undock! There was one remaining minor issue, though. With Access Connections 4.42 reinstalled, I started seeing a new issue where upon an undock, I would get an error dialog with caption "netsh.exe - Unable to Locate Component", and dialog text "This application has failed to start because framedyn.dll was not found. Re-installing the application may fix this problem." 
Fortunately (and unlike for the original "Applying wireless settings" failure issue), help was readily available via a Google search for this issue. Per a suggestion given in several of the search results, I copied the file framedyn.dll from my C:\Windows\system32\wbem folder to the C:\Windows\system32 folder; with this done, the error dialog now no longer appears.
At work yesterday, we were having a problem with one of our internal web applications running on BEA WebLogic Server 7 SP 7, Struts 1.1, and Java 1.4, where following an application redeployment, users of the application would get HTTP 500 errors. The WebLogic server output log file showed multiple ClassCastException errors with the following call stack:
java.lang.ClassCastException
at org.apache.struts.action.ActionServlet.getRequestProcessor(ActionServlet.java:871)
at org.apache.struts.action.ActionServlet.process(ActionServlet.java:1508)
at org.apache.struts.action.ActionServlet.doGet(ActionServlet.java:507)
at javax.servlet.http.HttpServlet.service(HttpServlet.java:740)
at javax.servlet.http.HttpServlet.service(HttpServlet.java:853)
. . .
at weblogic.servlet.internal.ServletRequestImpl.execute(ServletRequestImpl.java:2642)
at weblogic.kernel.ExecuteThread.execute(ExecuteThread.java:262)
at weblogic.kernel.ExecuteThread.run(ExecuteThread.java:224)
After some troubleshooting, we determined that this error would only occur when the application was under some load (from being hit by multiple users) while it was starting up; the error wouldn't occur if only a single user accessed the application while it was starting.
So, restarting the application while it was not under load (e.g. overnight) turned out to be a viable workaround in our case. Although we were back up and running at this point, I continued to research the issue to get a better understanding of the underlying cause, and to come up with a better solution should we ever need to restart the server during the work day in the future.
Researching the Issue
Some research via Google didn't turn up any obvious solutions on the issue. The exception was being thrown from the Struts class ActionServlet.getRequestProcessor; since Struts is open source, I decided to download the Struts source, and add some additional instrumentation to the getRequestProcessor method to see if that would shed any additional light on the issue.
ActionServlet.java line 871 (from the ClassCastException stack trace) turned out to be the second of these two lines, at the top of the ActionServlet.getRequestProcessor method:
String key = Globals.REQUEST_PROCESSOR_KEY + config.getPrefix();
RequestProcessor processor = (RequestProcessor)getServletContext().getAttribute(key);
So the exception was happening on the attempt to cast the result of getServletContext().getAttribute(key) to type RequestProcessor.
I added some logging to the getRequestProcessor method to log the class name of the result of the getServletContext().getAttribute(key) call to stderr (so that it would be visible in the WebLogic server log), along with the name of the current thread (so I would hopefully be able to get visibility into whether different application threads were getting different results).
Object o = getServletContext().getAttribute(key);
if (o == null)
{
  System.err.println("$$$ " + java.lang.Thread.currentThread().getName() + ": "
    + "getServletContext().getAttribute(key) is null");
}
else
{
  System.err.println("$$$ " + java.lang.Thread.currentThread().getName() + ": "
    + "type=" + o.getClass().toString());
}
(The "$$$" here is just a poor man's bookmark to let me easily search for my debug logging in the server log file.)
In the WebLogic log file, the type of the object causing the ClassCastException upon the attempt to cast it to type RequestProcessor was of type PIRequestProcessor, a custom type used by my company's application. I was initially confused by this, because PIRequestProcessor is declared to extend RequestProcessor in its class declaration, so casting a PIRequestProcessor to a RequestProcessor should be a valid operation. Yet this operation was definitely causing the ClassCastException.
At this point, I remembered a post on Java class loaders that I had just recently read on Kevin Bourrillion's blog (some slightly NSFW content). From Kevin's post:
But now we're finally getting to the interesting part: every class in memory in your runtime environment can be uniquely identified by the pair of
(a) its full name
(b) the class loader that loaded it
And also:
You may have heard someone explain, or you may have explained yourself, "see, you can't cast a foo.Bar to a foo.Bar here even though it's the same class, because they came from different class loaders, so there's funny class loader hoodoo going on there."
Aha! I improved my instrumentation on the getRequestProcessor method to include the classloader of the PIRequestProcessor instance, and of the current thread:
System.err.println("$$$ " + java.lang.Thread.currentThread().getName() + ": "
  + type=" + o.getClass().toString()
  + " | classloader of o: " + o.getClass().getClassLoader().toString()
  + " | current thread classloader: " + java.lang.Thread.currentThread().getContextClassLoader());
Sure enough, I got two sets of output in the log. One set like the following, for the first thread that got into the getRequestProcessor method, which looked like this:
$$$ ExecuteThread: '5' for queue: 'default': type=class com.gfs.mps.application.productInquiry.struts.PIRequestProcessor instanceof:true classloader of o: weblogic.utils.classloaders.ChangeAwareClassLoader@4b4b50 finder: weblogic.utils.classloaders.MultiClassFinder@6edffb current thread classloader: weblogic.utils.classloaders.ChangeAwareClassLoader@4b4b50 finder: weblogic.utils.classloaders.MultiClassFinder@6edffb
And another set of logged output, for the subsequent threads that get into getRequestProcessor, like this:
$$$ ExecuteThread: '7' for queue: 'default': type=class com.gfs.mps.application.productInquiry.struts.PIRequestProcessor instanceof:false classloader of o: weblogic.utils.classloaders.ChangeAwareClassLoader@4b4b50 finder: weblogic.utils.classloaders.MultiClassFinder@6edffb current thread classloader: weblogic.utils.classloaders.ChangeAwareClassLoader@dfb821 finder: weblogic.utils.classloaders.MultiClassFinder@1a1569b
(Bolded emphasis added by me; note the different class loader ID in the second log output.) The problem was that WebLogic was using two different class loaders in the different threads. The PIRequestProcessor[4b4b50] instance (i.e. a PIRequestProcessor instance created via the class loader with ID 4b4b50) was created and cached in the first thread in the call to getRequestProcessor. When the cached PIRequestProcessor was retrieved by the second thread in its call to getRequestProcessor, the PIRequestProcessor[4b4b50] instance was returned, and when the attempt was made to cast that to a RequestProcessor[dfb821] (created by the dfb821 class loader rather than the 4b4b50 class loader), the ClassCastException resulted.
Most likely this issue between Struts 1.1 and WebLogic Server 7 SP 7 has been addressed in the current versions of one or both products; both are fairly old versions of their respective products. (A poster in that BEA forum thread claims to have been sent a patch by BEA, CR189815, that resolves this issue in WebLogic 8.1.) But in the meantime, I still wanted to come up with a solution to the issue for our application running in that environment.
The Solution
In my initial research on Google, one of the items I had come across was an article on avoiding unnecessary JSP recompilations under WebLogic 8.1 on the BEA site by Nagesh Susarla. Among other things, the article mentions a WebLogic Server parameter, "servlet-reload-check-secs", which can be set to have WebLogic not monitor during runtime whether any new Java class files have been put into place. I also came across a thread in the BEA forums which mentioned someone else running WebLogic Server having a similar problem with a ClassCastException (not really in similar circumstances my own issue, but with a similar exception call stack) and with one of the replies suggesting that the WebLogic setting to disable to disable servlet reloading at runtime be set.
I decided to give that solution a try. Initially it wasn't obvious to me where the WebLogic 7 equivalent of the servlet-reload-check-secs parameter could be set, or even whether that parameter was supported at all under WebLogic 7; my web searches turned out some documentation on the setting for WebLogic 8.1, but not for earlier versions.
After some poking around in the WebLogic 7 console, I did find the place where the equivalent of "servlet-reload-check-secs" can be set: The setting is called "Reload Period", located in the console at [domain] | Deployments | Web Applications | [app name] | Configuration tab | Files sub-tab. The setting's default is 1; setting the value to -1 and restarting the WebLogic server disables WebLogic's runtime servlet reload checking for the web application where the setting was made. (The underlying WebLogic domain config.xml setting is called "ServletReloadCheckSecs".)
After making that setting change, things started working correctly! In my log, I could see that WebLogic was no longer using different class loaders in calls to the Struts ActionServlet.getRequestProcessor method; therefore, no ClassCastException was occurring, and the application was loading properly.
For a while now, I've known that you can launch the Paint image editor that is bundled with Windows by typing either one of mspaint or pbrush at the Start | Run dialog. I was recently using my PathFind utility (a which-like command-line utility that shows where a specified file is located on the path) to check on the locations of a few Windows programs, and I used it to find the locations of mspaint.exe and pbrush.exe on my Windows XP machine.
As expected, PathFind.exe showed that mspaint.exe was located at C:\Windows\system32. But when I had PathFind look for pbrush.exe, to my surprise, it reported that the file was not located anywhere on the path.

At this point, I got pretty curious about how running pbrush.exe from Start | Run was launching Paint when pbrush.exe apparently didn't exist on the path, and some brief searching on Google and Google Groups didn't reveal any answers, so I decided to don my Mark Russinovich-style Detective Hat and do some investigation to figure out just what was going on!
I tried using PathFind to search for "pbrush.*" to see if it was running from a filename with some other extension, such as pbrush.com. However, no file named pbrush with any extension existed on the path.
I still wasn't convinced that pbrush.exe didn't exist somewhere on the machine, so I hit Win+F to bring up Windows' built-in search, and searched my entire hard drive for files with "pbrush" in the name. However, even that search turned up 0 results. To all appearances, there simply was no file named pbrush present anywhere on the machine.
I did notice, by bringing up Task Manager, that the actual executable that was being launched was always mspaint.exe, even when I was entering pbrush in the Run dialog to launch the program. I was still curious, though, how running pbrush (which to all appearances did not exist) could cause the mspaint.exe file to be launched.
I started up Filemon and set up a filter to show only references to "pbrush", then launched pbrush.exe from Start | Run.

Interestingly, Filemon showed only a single "not found" error for pbrush.exe. Normally, Filemon will show a "not found" error for every directory in the path when an attempt is made to run a program with a filename that doesn't exist. So in this case, it appeared that Windows was looking in just the C: drive for pbrush.exe, and then doing "something else" which resulted in Paint being launched, before Windows went on to look for pbrush.exe on the path.
I then ran Regmon, again filtering on "pbrush", and ran pbrush.exe once again.

Aha! In line 6 of the Regmon output, I could see some kind of mapping from pbrush.exe to mspaint.exe. I figured that this must be the link between pbrush.exe (which I was running from the Run dialog) and mspaint.exe (the app that was actually getting launched) that I was looking for. So I decided to take a look at the HKLM\Software\Microsoft\Windows\CurrentVersion\App Paths registry key.
I opened up Regedit and navigated to My Computer\HKEY_LOCAL_MACHINE\SOFTWARE\Microsoft\Windows\CurrentVersion\App Paths.

At that location, I found a key for pbrush.exe, along with many other keys with names of .exe filenames, many of them familiar. By doing a bit of experimentation, I was able to conclude that the App Paths key acts as a sort of map that Windows uses to find the location of an executable file being run.
For most of the App Paths keys, the (Default) value for the key mapped to the full path to the executable of the same name; for example, on my machine, the Winword.exe key mapped to "C:\PROGRA~1\MICROS~2\OFFICE11\WINWORD.EXE", the actual location of the Microsoft Word executable. (As I discovered, this is why entering winword at the Start | Run dialog successfully launches Word even though the Office11 folder isn't on the path.) In the case of the pbrush.exe key, though, the mapping was to the location of mspaint.exe; thus, running pbrush resulted in mspaint.exe, the Paint program, being launched. Mystery solved!
From some newsgroup posts that I came across while researching this issue, apparently on Windows 9x series machines (e.g. Windows 98), a pbrush.exe file actually was included in the system32 directory that was just a stub which executed mspaint.exe. (In even older Windows versions, pbrush.exe was the 16-bit version of the Paint program; the 32-bit version, mspaint.exe, was apparently introduced with Windows 95.) For the 32-bit Windows NT series, an engineer at Microsoft must have decided to switch the pbrush command from working via the actual pbrush.exe stub file to taking advantage of the HKLM\Software\Microsoft\Windows\CurrentVersion\App Paths registry key.
|
|




 Posts

